Talk to us
Picking Brains · Vol.
11
“Be intentional. Nothing should be random.”
Veronica Nadler, Data Engineer at Redeploy, on what makes data AI-ready, what tripped up her own model, and why knowing the data is key.
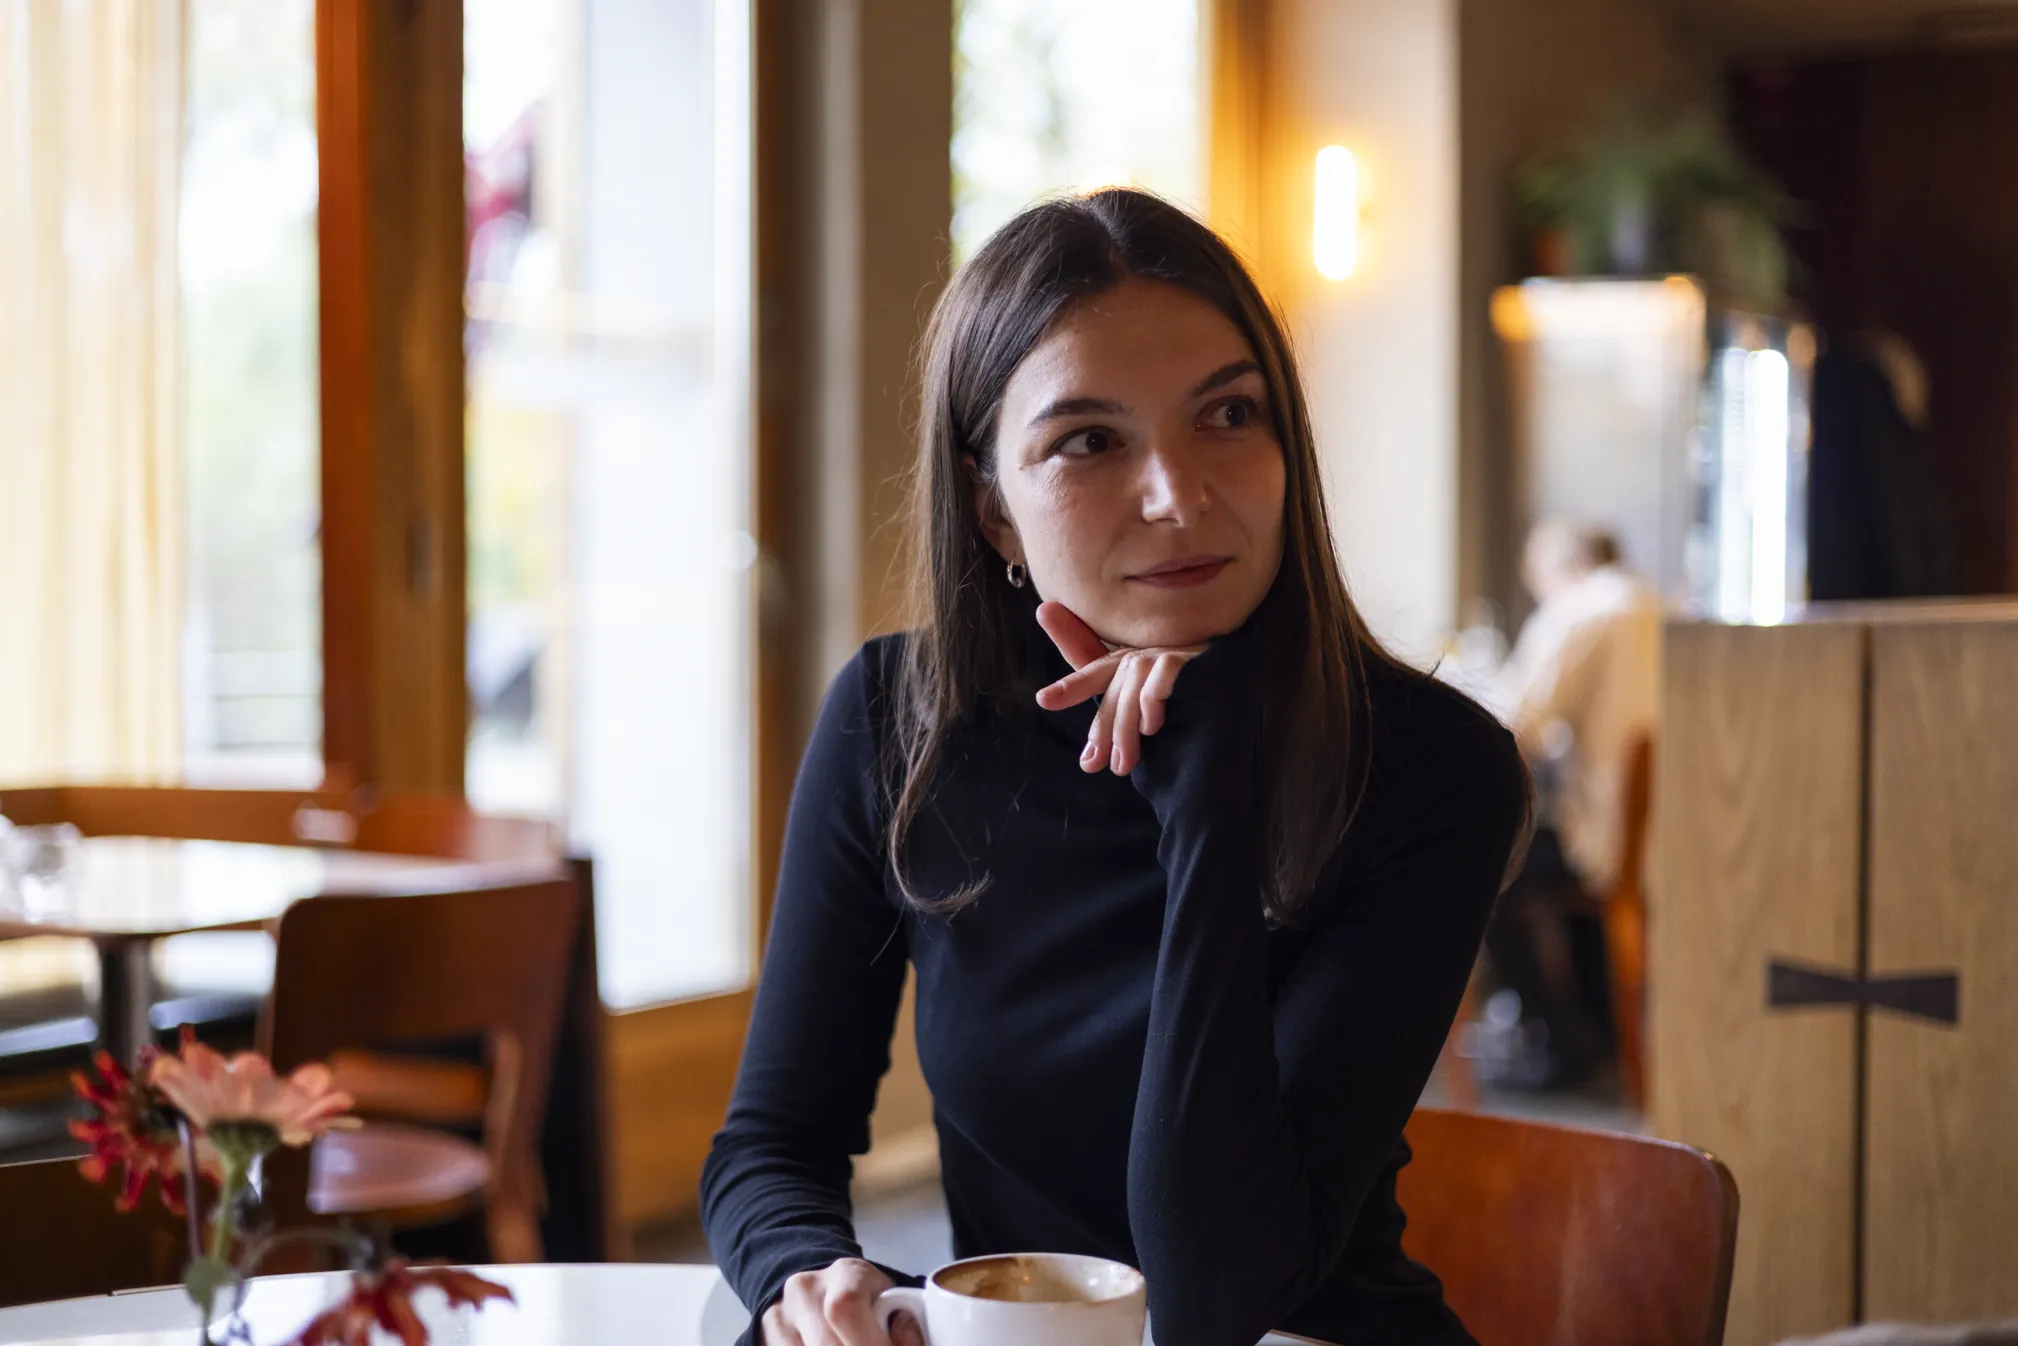
Veronica builds data platforms, a digital hub for a company's information. A lot of her job, she says, is translating between business language and tech language.
Picking Brains is our interview series with the people who build Redeploy's platforms. In volume 11 Veronica invited us for a coffee at her favorite place, Bio Rio, to talk about AI-ready data, messy data and how her role has changed.
What does a data engineer actually do?
I build and manage data platforms, a digital hub for a company's information. I write scripts that take in data from Excel files, salary software or websites, then clean and deduplicate it. All automated, so new data flows from the source into a neat, analysis-ready format. A lot of the job is translating between business language and tech language.
What does AI-ready data mean to you?
It's not so different. Algorithms need structured, consistent data, and that's what we do. But machine learning can be sensitive to skewed data and outliers, so we look into them first. Is it a data quality issue or valid data? Knowing the data is key.
AI-ready data
“Organized, structured, well-understood data is the foundation of everything.”
Veronica Nadler
Data engineer
When has messy data tripped up an AI model for you?
In my bachelor's thesis we fine-tuned our own model for second-hand pricing. The question was how much we could automate without humans. The answer was, we can't get around it. Attributes were missing, and the same brand could vary a lot in price. Humans know it's probably the condition. The model didn't. We have to give it more context.
How has your role changed since AI took off?
Debugging takes so much less time and tears. I've learned tons about using agents, and it's a lot of the same principles as with data: be clear and precise. But the foundation is still data and infrastructure, so I learn everything I can there. Databricks first, then Fabric, and now Azure and landing zones. There's always something to learn.
Fact box
How we build AI-ready data platforms
Our data platforms are open across Azure, AWS, Databricks, and Fabric, so you keep the choice. We store your data once in an open lakehouse and make it AI-ready with quality checks, structure, and a semantic layer. Governance, lineage, and access are part of the build. Everything is infrastructure as code, so the platform is repeatable and reviewable.

Veronica invited us for a coffee at her favorite place, Bio Rio
Using AI
“Nothing is done on first draft though. AI-generated work gets tested and validated like everything else.”
Veronica Nadler
Data engineer
How do you use AI in your own work?
It's my sounding board, and it handles tedious refactoring and speeds up research. Once, a single value in a report didn't add up. With AI we traced it to a filter the client thought they needed, and it turned out to be the error. Nothing is done on first draft though. AI-generated work gets tested and validated like everything else.
What's your top advice for AI-ready data?
Be intentional. Nothing should be random. If information is scattered across spreadsheets, a Word document here and a PDF there, you have to process it more. That takes clear ownership, and managers have to embrace it. No need for anything fancy, just reliable collecting and organizing.
Data Platform
Make your data AI-ready
Veronica's advice is to be intentional with your data. Our Data Platform is the governed, AI-ready foundation your analytics and AI both run on.
Explore Data Platform