Talk to us
Picking Brains · Vol.
8
“Before you ask what AI can do for you, ask whether you can trust your data”
Efstathios Sidiropoulos, Data Engineer at Redeploy, on the plumbing behind every report, model and AI initiative, and why it has to be in place first.
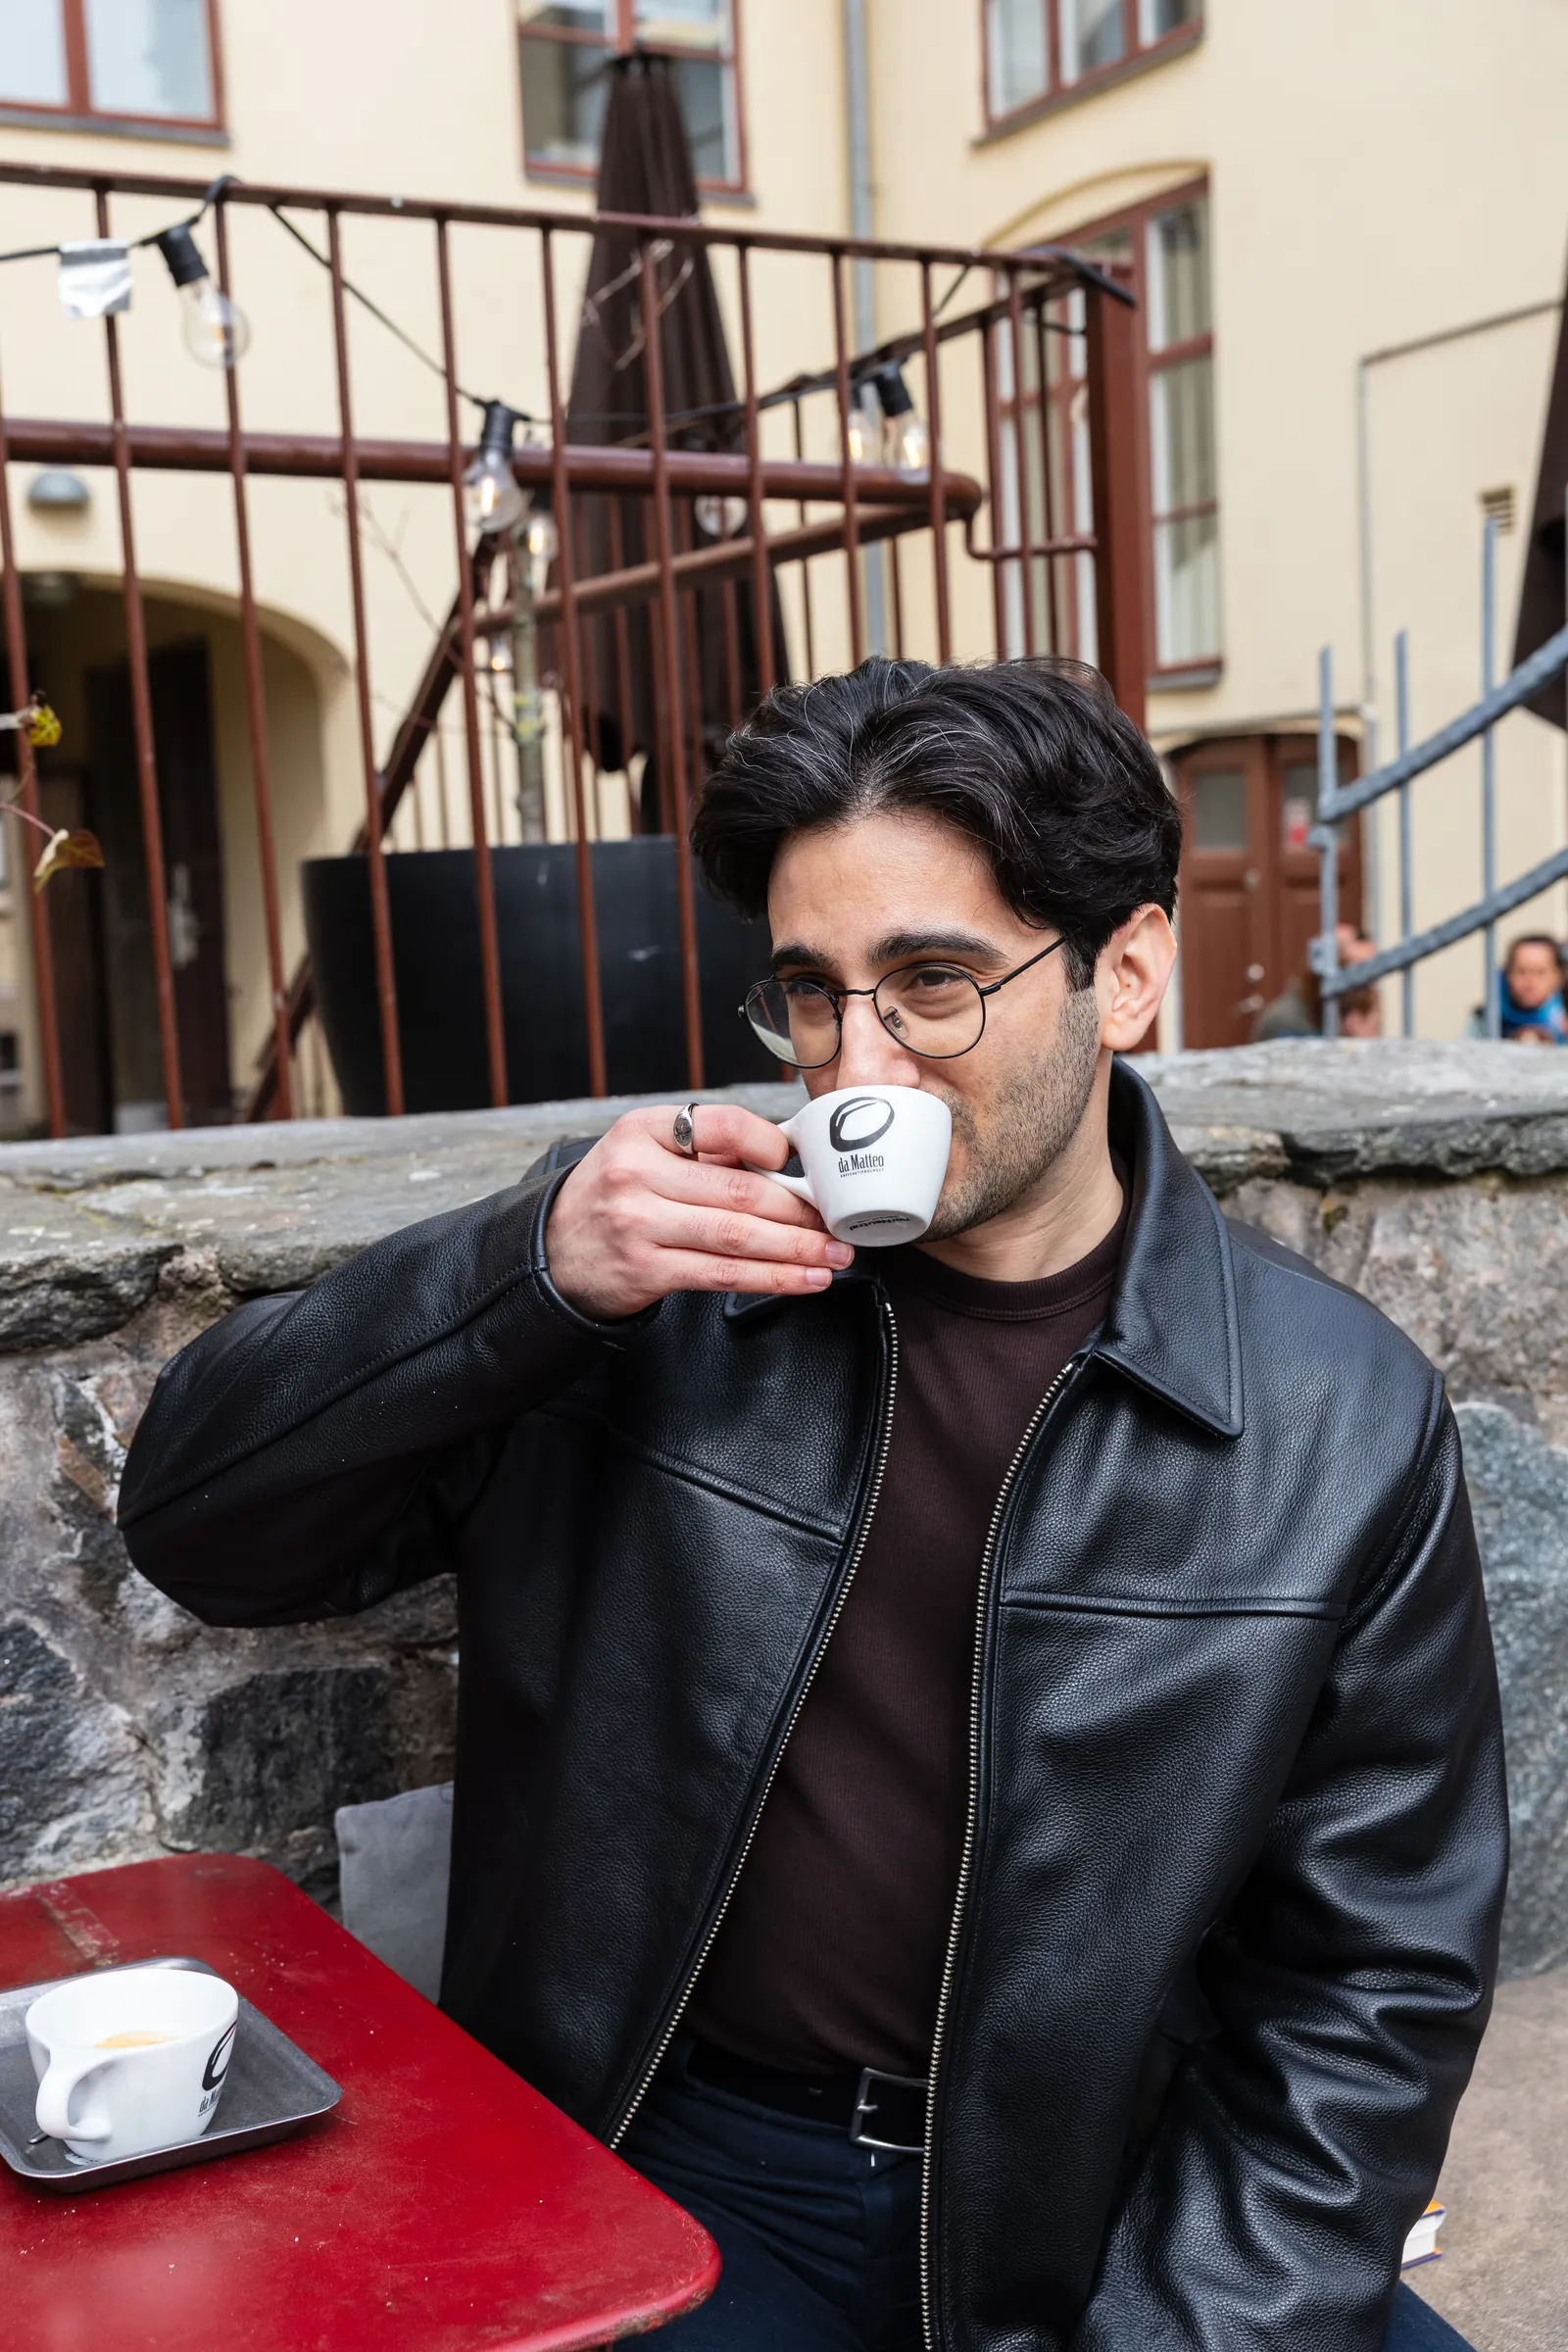
Efstathios came to data engineering from a business background. That shows in how he works: half the job, he says, is understanding what the data needs to mean, not just how to move it.
Picking Brains is our interview series with the people who build Redeploy's platforms. In volume 8 we sat down with Efstathios over coffee to talk pipelines, medallion architecture and the biggest mistake organizations make when they scale AI.
What do you do as a data engineer?
Making sure data gets from where it's created to where it's needed, reliably, cleanly, on time. Think of it as the plumbing of an organization. Without it, nothing downstream works. Not your reporting, not your analytics, not your AI.
What challenges do you encounter daily?
The problems that land on my plate are usually at the intersection of technical and organizational. Data in someone's Excel file. Business logic that exists only in someone's head. Governance nobody has formally defined. I make implicit things explicit, so stakeholders go from slow, manual processes to reporting they can trust.
From business to engineering
“Coming from a business background before moving into engineering, I often find that half the job is understanding what the data needs to mean, not just how to move it.”
Efstathios Sidiropoulos
Data engineer
What's your go-to tech right now?
Databricks. And lately I've been working a lot with Databricks Asset Bundles, which brings proper DevOps practices into data engineering. Version control, history tracking, and the ability to revert if something goes wrong.
What does a good data architecture look like?
It's case-to-case, but we typically use a medallion architecture, with raw data through bronze, silver, and gold layers, each cleaner and more aggregated than the last. If it's an analytics report, you clean in silver and aggregate in gold. If feeding a model, you may need clean, null-free data going into inference.

Good company, says the book
Every layer counts
“You cannot have analytics without data. And if you can't do descriptive analytics, you're not ready for machine learning or AI. Every layer depends on the one beneath it.”
Efstathios Sidiropoulos
Data engineer
What's the role of data engineering in the AI era?
It's foundational. AI and machine learning don't work without clean, reliable data flowing through a well-built pipeline. The model doesn't care how clever the algorithm is if the input is garbage. Data engineers make sure that doesn't happen, and the role is only becoming more important as demand for quality data goes up.
The biggest mistake you see when organizations scale AI?
They invest in AI before they've invested in their data. They buy the tools, hire talent, build a PoC, then hit a wall, because the data underneath isn't ready. It's not clean, it's not governed, it's not trusted. Before you ask what AI can do for you, ask whether you can trust your data. That question alone changes the conversation.
Data Platform
Data you can trust, before the AI
Redeploy builds data platforms on Azure Databricks: governed, version-controlled, and ready for analytics, machine learning, and AI.
Explore Data Platform